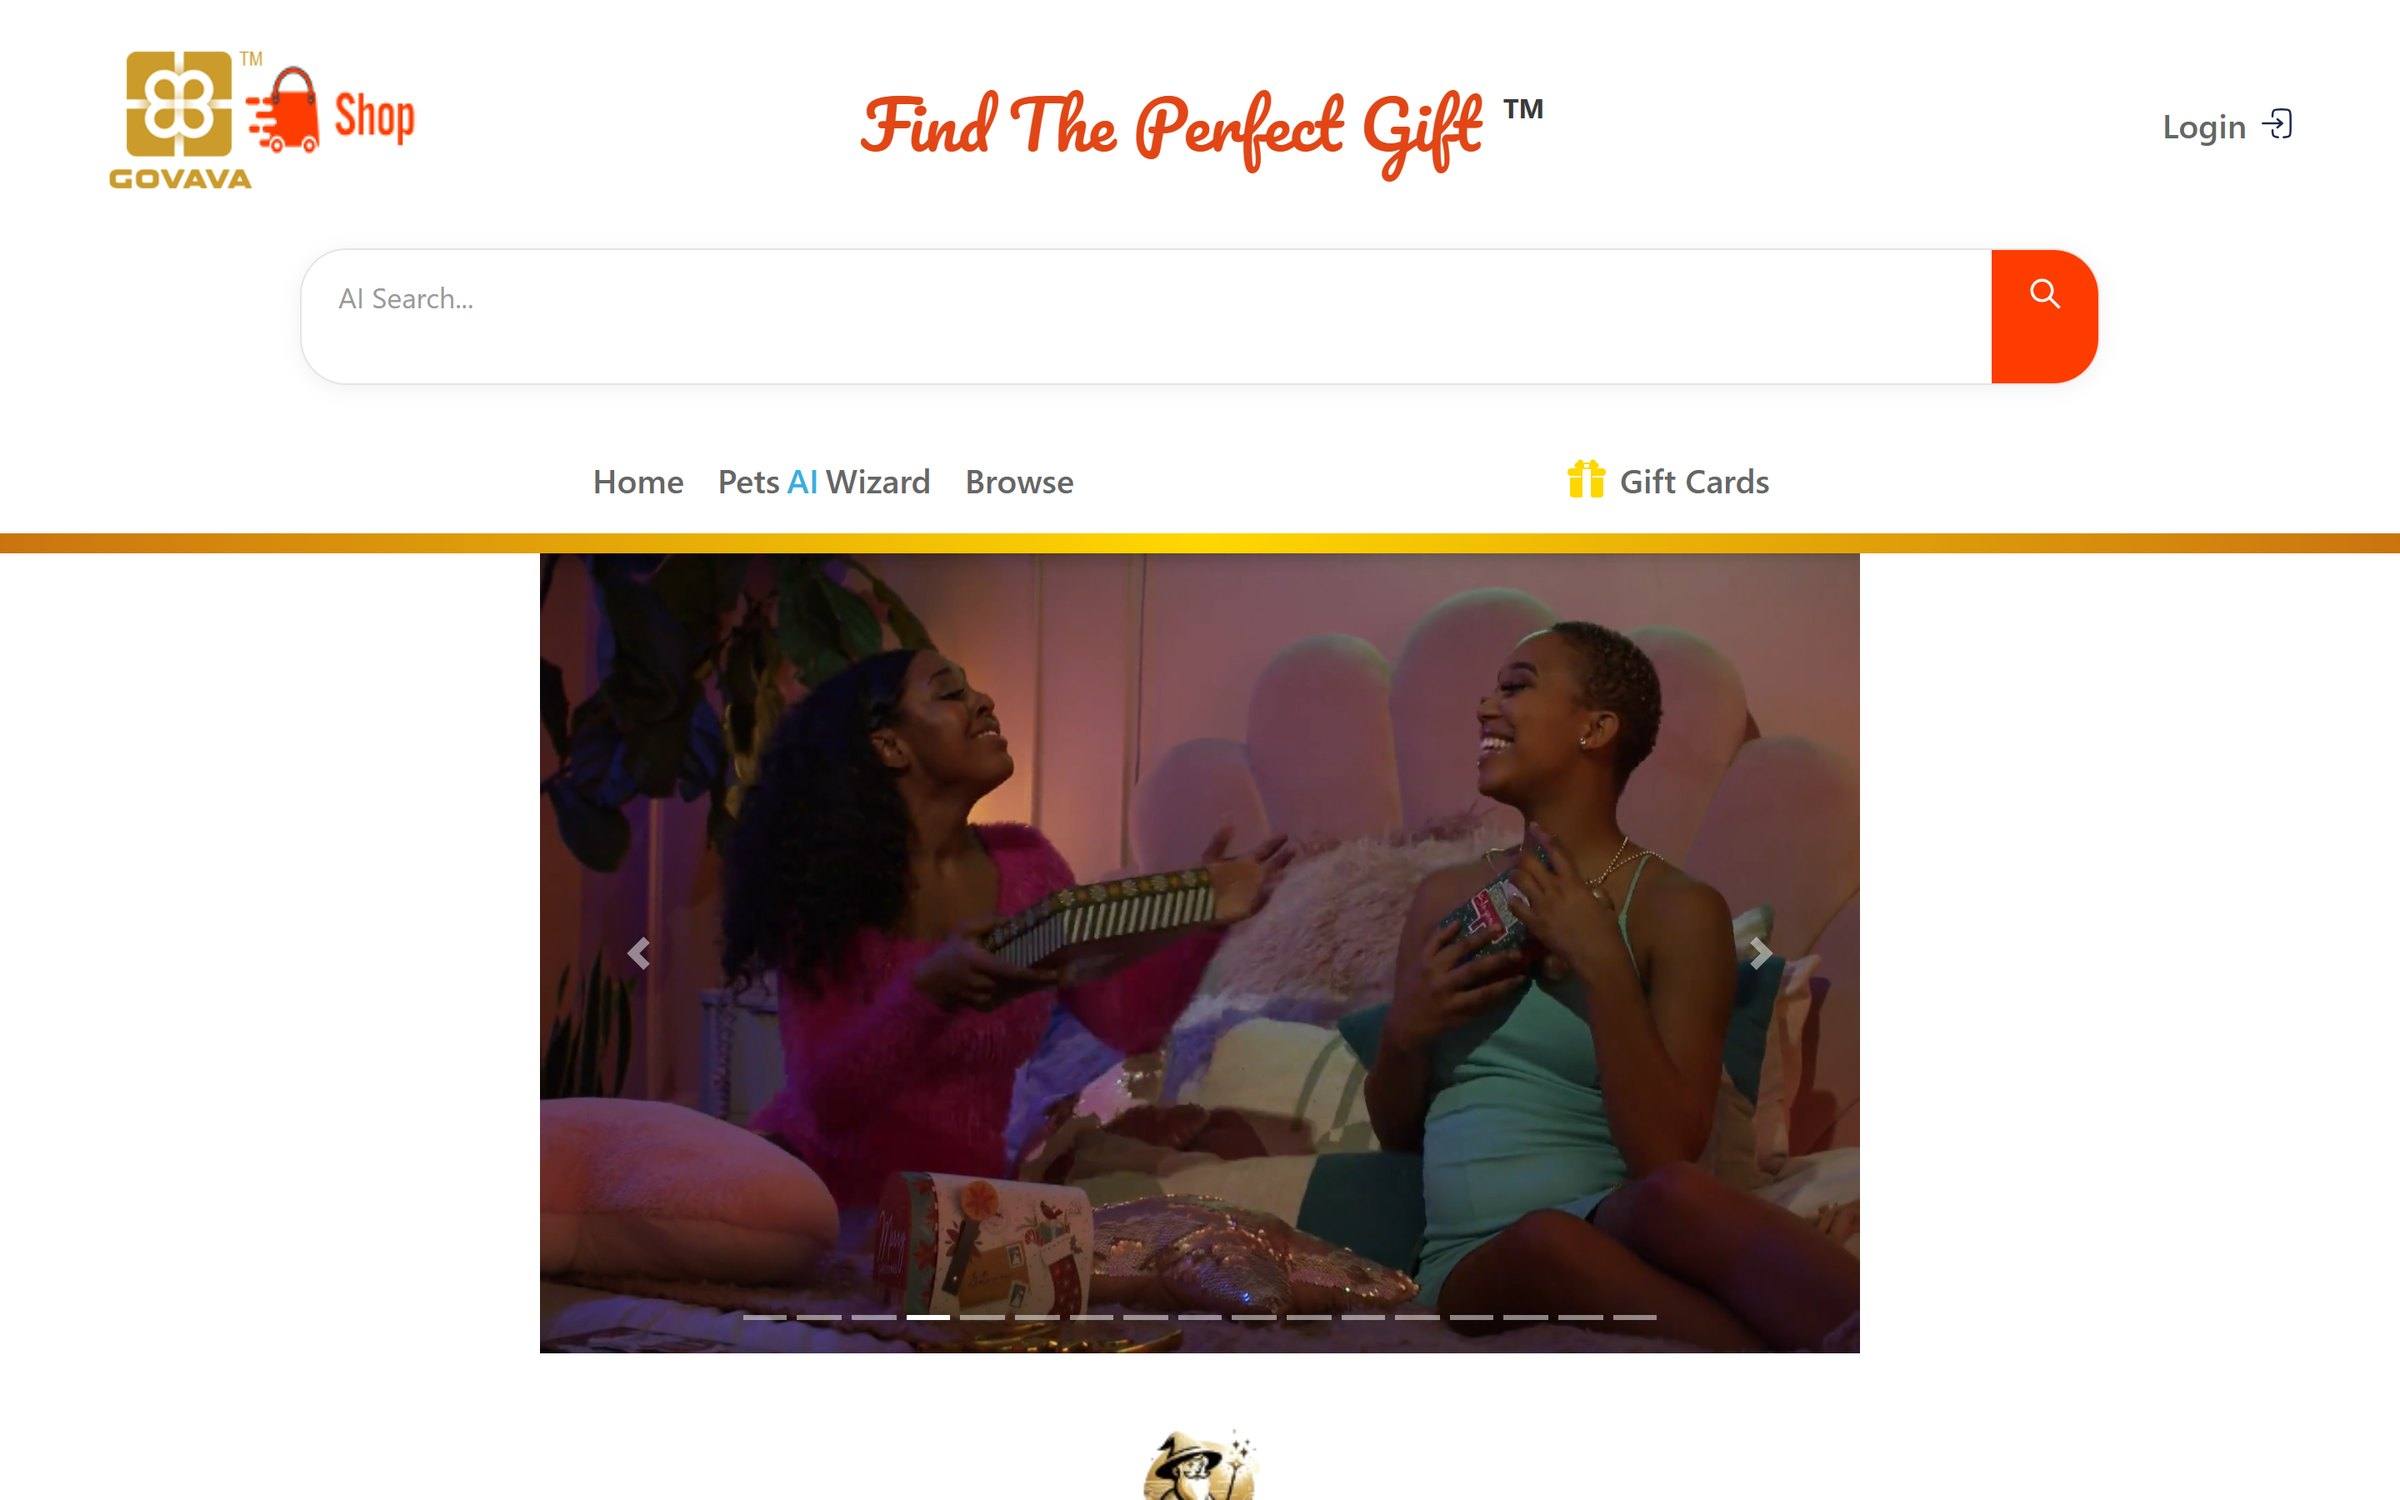
Govava is a gift-shopping site with an AI search box. I built the retrieval-augmented search behind it, and the pipeline that collects and cleans the product data it searches.
Keyword search over a huge product catalog returned poor matches. The catalog was the other half of the problem: tens of millions of records from different marketplaces, each with its own format, duplicates and noise.
02 — Build
What I built
A large-scale scraping and cleaning pipeline over tens of millions of product records from Amazon, Walmart, Rakuten, Etsy and other marketplaces.
Embeddings and Elasticsearch indexing over the cleaned catalog.
RAG search on AWS Bedrock that matches a shopper’s plain-language request to relevant products.
Queue-based processing on AWS to keep ingestion running at that scale.
03 — Architecture
How it works
Listings are cleaned, embedded and indexed ahead of time. Each search retrieves from that index first, so the model answers from real products.
04 — Outcome
Results
Search relevance improved significantly over keyword search.
Tens of millions of product records processed and indexed.
Running in production at govava.com.
05 — Stack
Built with
Python
AWS Bedrock
Vector embeddings
Elasticsearch
AWS
Next step
Let’s talk.
Want something like this built, or hiring for a role? I’m open to both.